AI Explained
Plain explanations of trending AI concepts, with live visualizations.
Role-Agent paper — One LLM as agent and environment — What does it mean?
Role-Agent trains an agent by making one LLM play both the agent and the world it acts in — no external environment, no separate reward model.
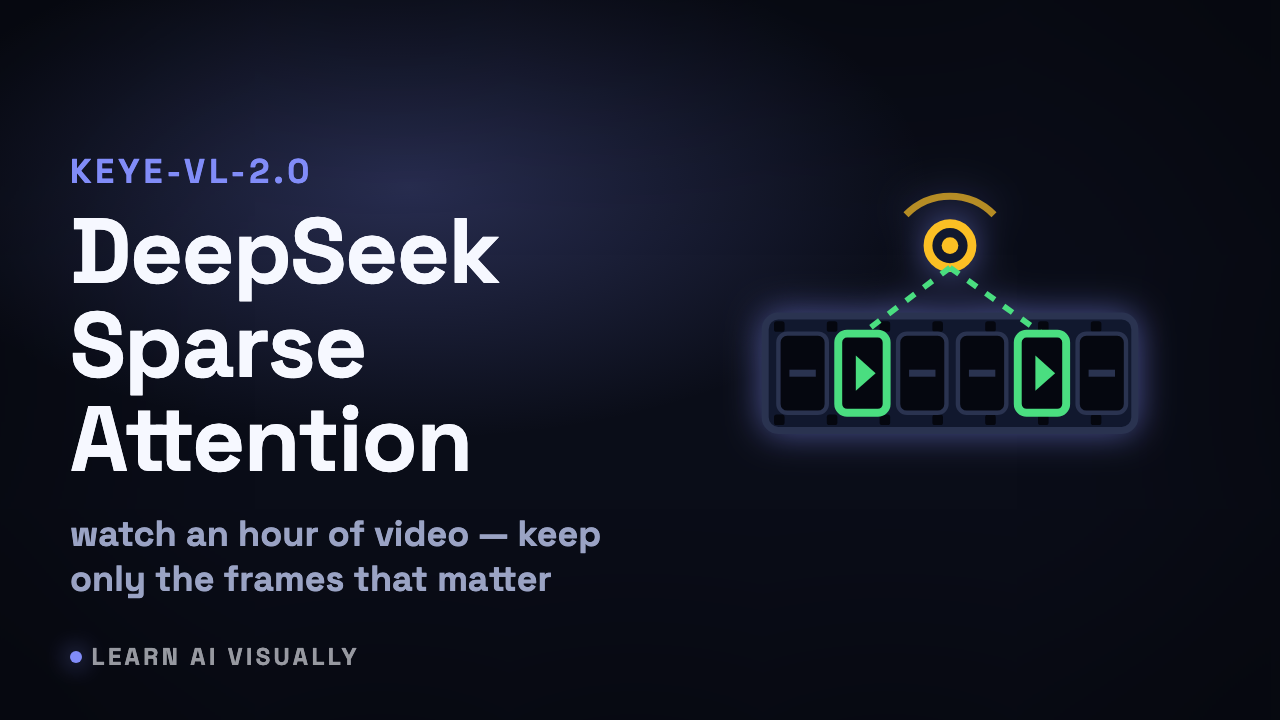
Kwai Keye-VL-2.0 — DeepSeek Sparse Attention for video — What does it mean?
Keye-VL-2.0 ports DeepSeek Sparse Attention to video: a cheap 'lightning indexer' picks the few frames each query needs, keeping a 256K context lossless.
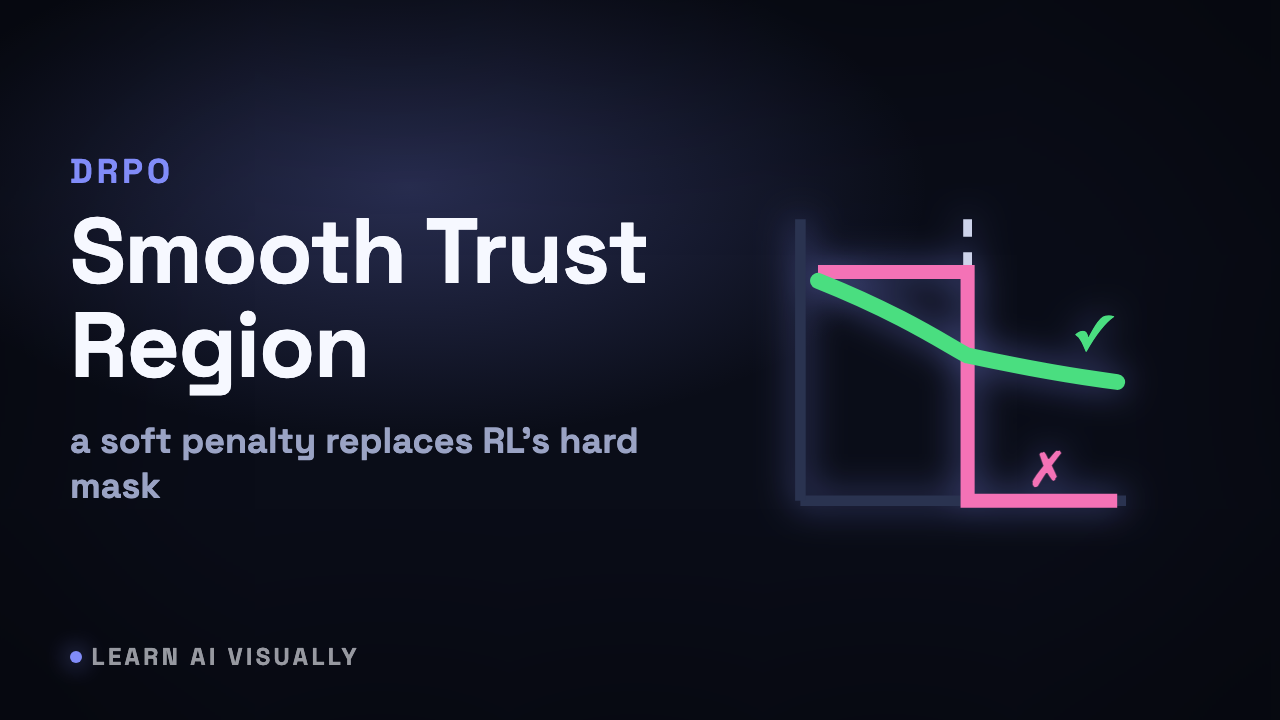
DRPO: smooth trust-region regularizer replaces hard masks in LLM RL — Corrective gradients past the boundary — What does it mean?
DRPO swaps RL's hard trust-region mask for a smooth, advantage-weighted penalty — a diverging token gets pulled back, not dropped.
SearchSwarm hits SOTA on BrowseComp with a 30B agent — Distilling delegation into the weights — What does it mean?
SearchSwarm bakes task decomposition and subagent delegation into a 30B model's weights via SFT — not prompts — and tops BrowseComp.
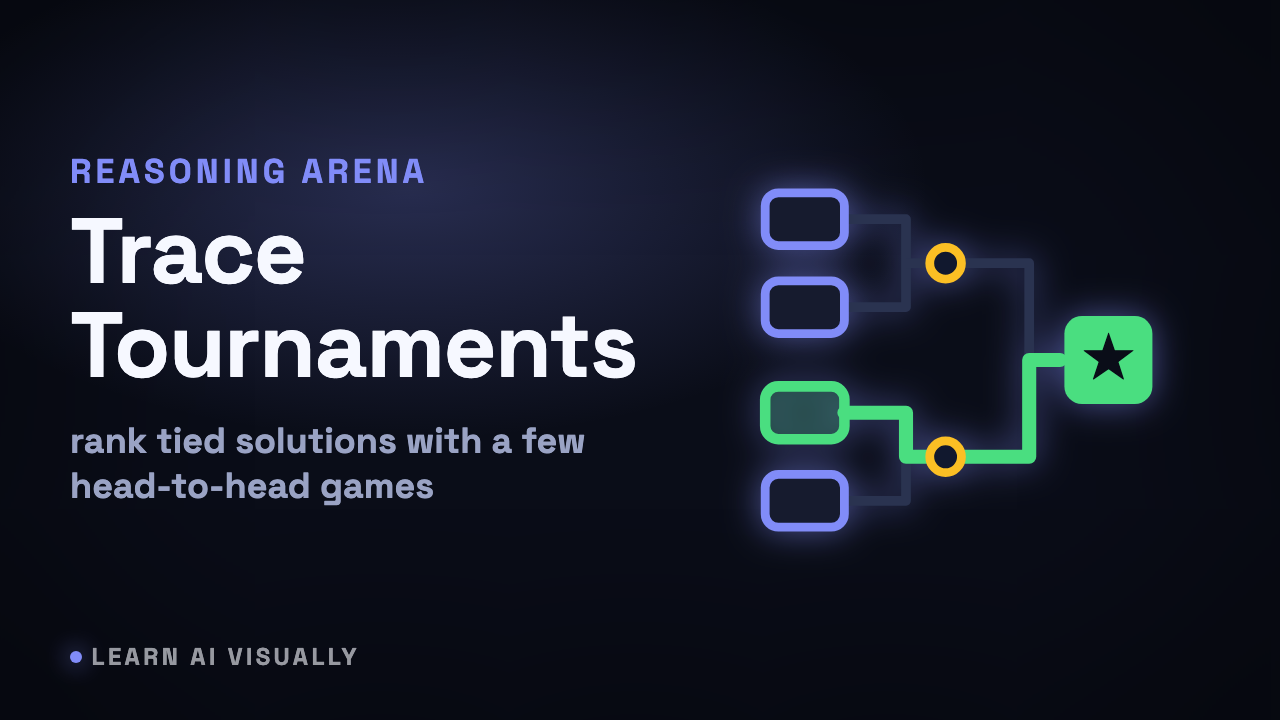
Reasoning Arena adds trace tournaments where RL verifiable rewards tie — Bradley-Terry trace ranking — What does it mean?
Reasoning Arena breaks RLVR reward ties by judging tied reasoning traces in a pairwise tournament and ranking them with a Bradley-Terry model.
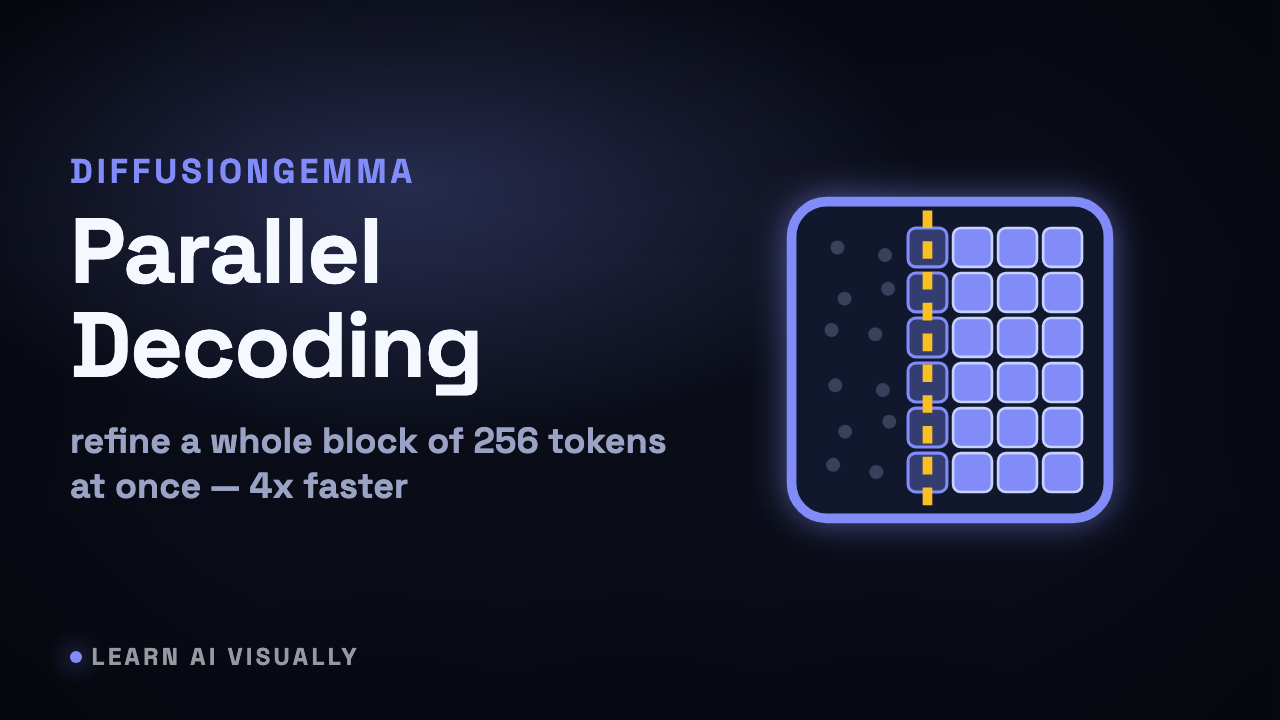
Google releases DiffusionGemma — Parallel block decoding — What does it mean?
DiffusionGemma writes text by refining a whole block of 256 tokens at once — parallel block decoding, up to 4x faster than autoregressive Gemma.
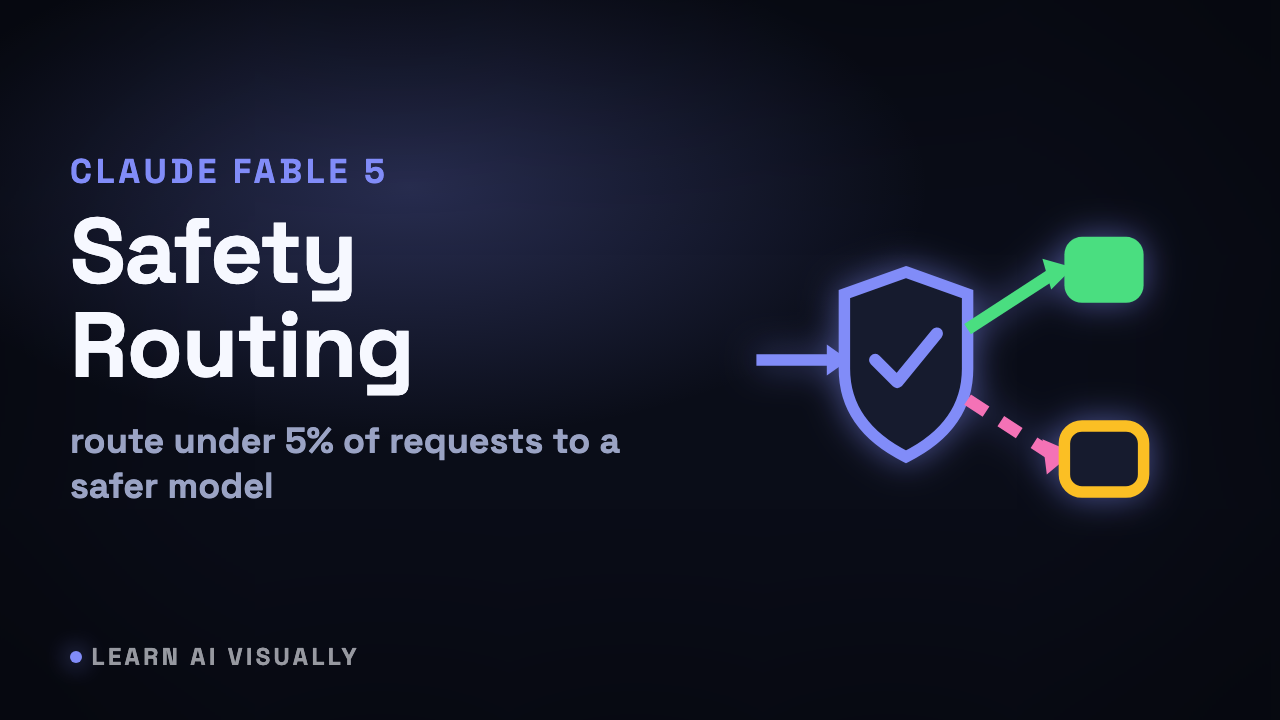
Anthropic's Claude Fable 5 & Mythos 5 — Safety-routing fallback classifiers — What does it mean?
Fable 5 ships a frontier model to everyone by routing under 5% of sensitive requests to a more conservative model instead of weakening it.
Attention Amnesia: CoT fine-tuning wrecks long-range recall in hybrid LLMs — Training-free QK-Restore — What does it mean?
Fine-tuning a hybrid LLM to reason silently breaks long-range recall; QK-Restore rolls back just the Q/K projections to recover it — no retraining.
Latent Context LMs compress prompts 16x — Encoder-decoder prompt compression — What does it mean?
Latent Context LMs use a small encoder to squeeze a long prompt into a 16x shorter sequence of latent embeddings a decoder reads as tokens.
Google releases Gemma 4 12B — Encoder-free multimodal projection — What does it mean?
Gemma 4 12B drops the separate vision and audio encoders — image patches and audio go straight into the token stream, no ViT.
FlashMemory cuts DeepSeek-V4's KV cache to 13.5% — Lookahead Sparse Attention — What does it mean?
FlashMemory's Lookahead Sparse Attention trains a small indexer to keep only the KV-cache chunks a token will use — shrinking the physical cache to 13.5%.
Chiaroscuro Attention cuts attention FLOPs 62% — Spectral-entropy token routing — What does it mean?
Chiaroscuro scores each token's spectral entropy and sends most tokens through a cheap frequency-domain mixer, paying full attention only for the few.