AI Explained
Plain explanations of trending AI concepts, with live visualizations.
NVIDIA Blackwell sweeps MLPerf Training 6.0 — Strong scaling — What does it mean?
Strong scaling asks if 2× the GPUs really halves training time. MLPerf 6.0: 8,192 Blackwell GPUs trained DeepSeek-V3 671B to target in 2.02 min.
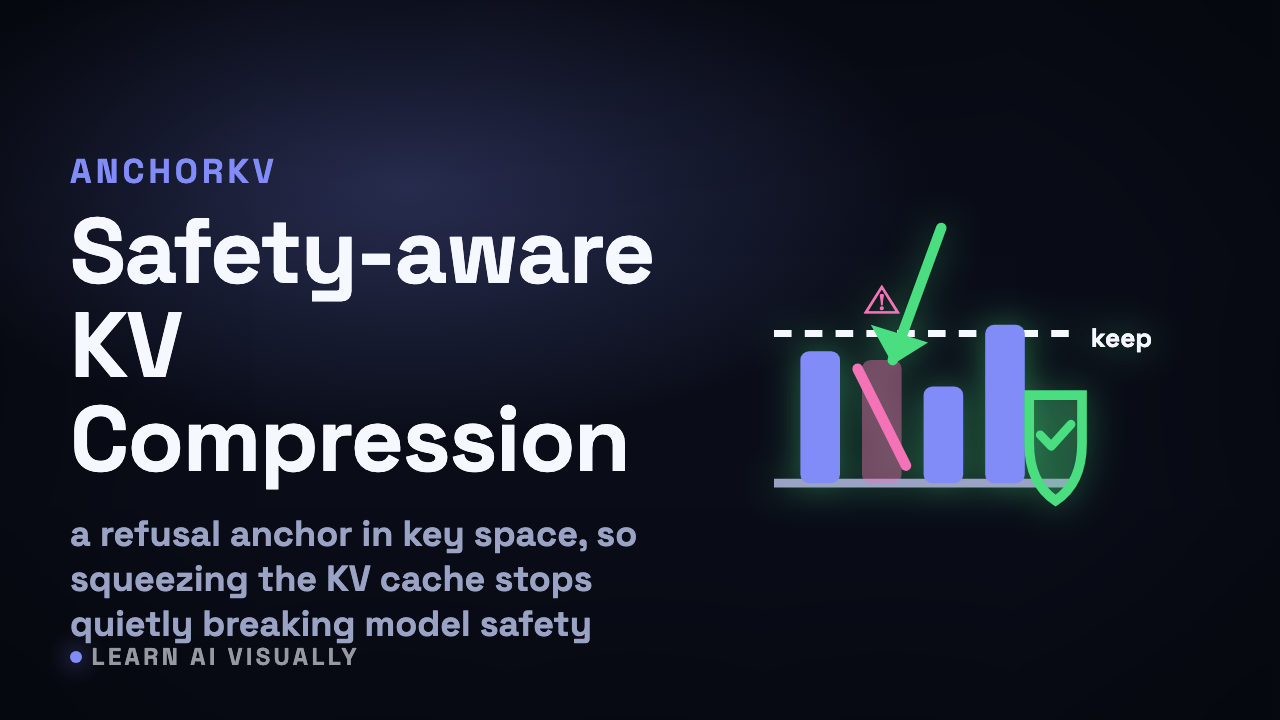
AnchorKV makes KV-cache compression safety-aware — Refusal anchor in the KV cache — What does it mean?
AnchorKV gives KV-cache eviction a safety-aware penalty, so compressing the cache to save memory no longer quietly erodes a model's alignment.
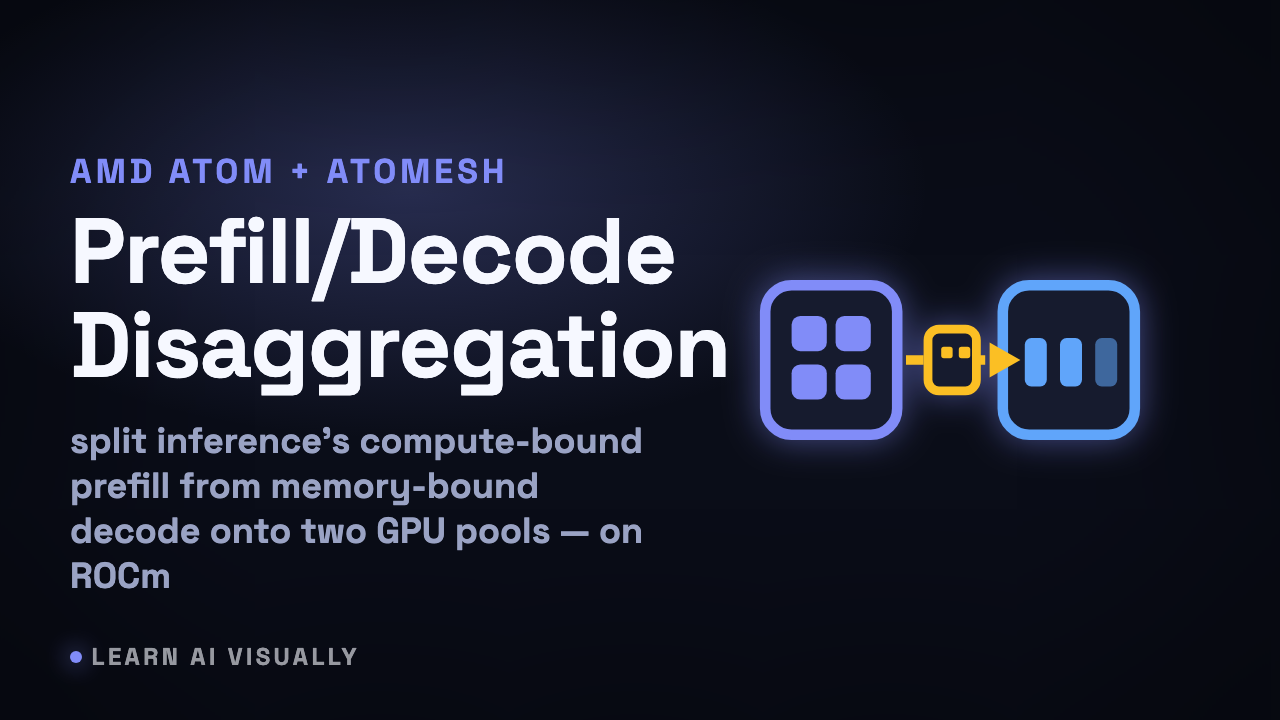
AMD ATOM + ATOMesh — Prefill/decode disaggregation on ROCm — What does it mean?
AMD's new ROCm serving stack splits LLM inference into a compute-bound prefill phase and a memory-bound decode phase, running each on its own pool of GPUs.
Variable-width transformers cut FLOPs 22% — Hourglass layer width — What does it mean?
A transformer with wide outer layers and a narrow middle — an hourglass — cuts 22% of FLOPs and 15% of KV-cache at matched loss.

Ternary Mamba compresses an SSM 3.6x with 4 GPU-hours of QAT — Ternary quantization-aware training — What does it mean?
Ternary Mamba forces every weight to -1, 0, or +1 and trains on that grid, shrinking a Mamba SSM 3.6x in 4 GPU-hours.
SoftMoE replaces top-k expert routing — Differentiable soft top-k routing — What does it mean?
SoftMoE swaps a mixture-of-experts' hard top-k router for a differentiable soft top-k, so the router learns straight from the task loss.
PreAct compiles agent runs into replayable programs — Compiled trajectory replay — What does it mean?
PreAct compiles an agent's successful run into a replayable program it re-runs with no per-step model call — 8.5–13× faster on repeats.
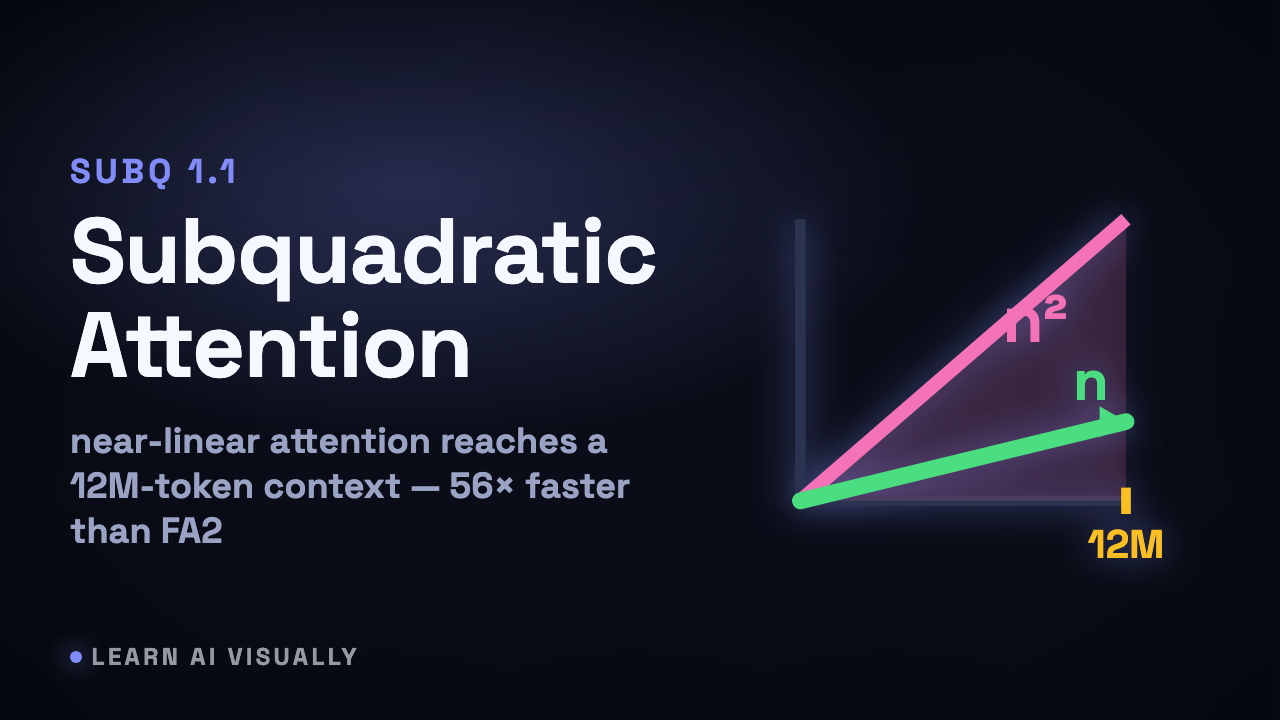
SubQ 1.1 Small hits a 12M-token context — Subquadratic sparse attention — What does it mean?
SubQ 1.1 trades dense n² attention for a near-linear sparse form — a 12M-token context, 56× faster than FlashAttention-2 at 1M.
VibeThinker-3B hits 94.3 on AIME 2026 — Diversity-driven RL — What does it mean?
Diversity-driven RL keeps a model's solution strategies wide instead of collapsing onto a few — how a 3B model reaches 94.3 on AIME 2026.
Microsoft FastContext: a repo-explorer subagent cuts coding-agent tokens 60% — Explorer-subagent context offloading — What does it mean?
FastContext trains a separate read-only explorer subagent that finds code and returns citations, cutting a coding agent's tokens up to 60%.
AdaSR teaches LLMs to reason mid-stream — Streaming reasoning — What does it mean?
AdaSR trains LLMs to reason while input still streams in, then deliberate once it lands — split-phase RL credit under a latency-aware reward.
SIMMER: 56% of frontier-LLM plans hide latent failures — Latent failures in planning — What does it mean?
A latent failure is a plan that runs to the end without erroring and still silently fails the goal — SIMMER finds up to 56% of LLM plans hide one.