AI Explained
Plain explanations of trending AI concepts, with live visualizations.
OpenThoughts-Agent open-sources a 100K-example agent training recipe — Task-source diversity in agent SFT — What does it mean?
OpenThoughts-Agent's open 100K-example agent-SFT recipe shows task-source diversity, not raw data volume, is what makes agents broadly capable.
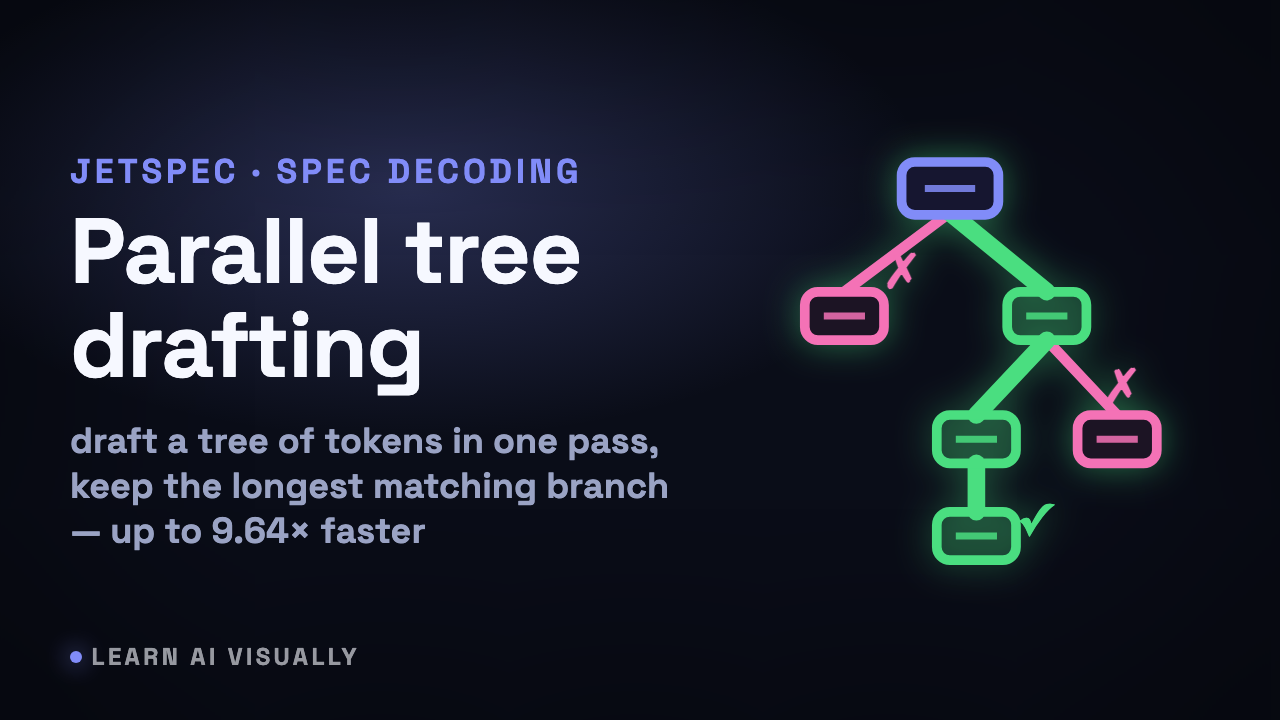
JetSpec speeds speculative decoding up to 9.64× — Parallel tree drafting — What does it mean?
JetSpec drafts a tree of candidate tokens in one pass, turning a bigger draft budget into longer accepted runs — up to 9.64× faster decode.
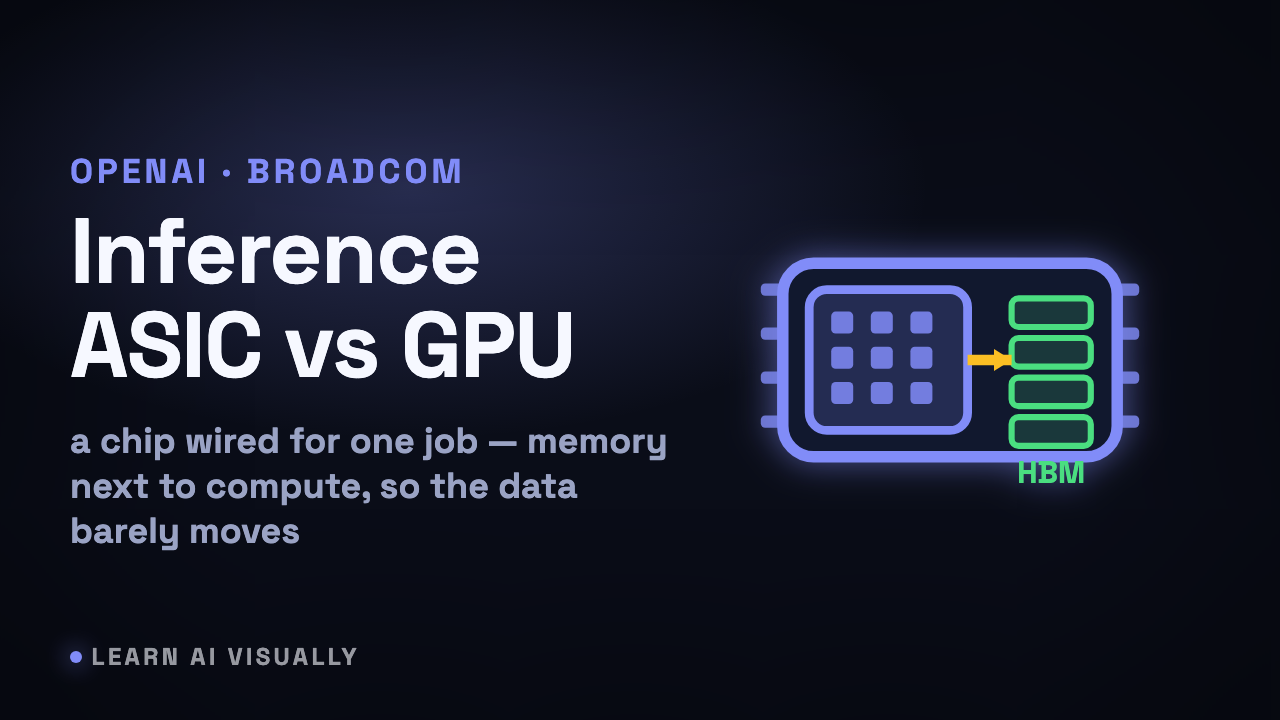
OpenAI and Broadcom's Jalapeño, a custom inference ASIC — Inference ASIC vs GPU — What does it mean?
OpenAI and Broadcom's Jalapeño runs LLM inference only, trading a GPU's flexibility for a shorter, faster path from memory to compute.
Routing, voting, and mixture-of-agents hit a shared ceiling across 67 models — Co-failure ceiling — What does it mean?
When every model misses the same question, no router, vote, or mixture-of-agents can recover it — and that shared-failure rate is ~2.5× higher than correlation predicts.
WorldKV — Evict-and-reinsert KV memory — What does it mean?
WorldKV evicts KV chunks to camera-indexed storage and reinserts them on revisit, bounding a video world model's cache at ~2x throughput.
MiniMax-M2 ships a 230B open MoE with 40× faster RL training — Forge RL prefix-tree merging — What does it mean?
MiniMax-M2's Forge RL merges rollouts that share an opening into one tree, so the shared work runs once — a reported 40× training speedup.
Agentic CLEAR grades agents at three zoom levels (IBM) — System/trace/node eval granularity — What does it mean?
Agentic CLEAR reads traces your agent already logs and writes an LLM-judge diagnosis at three zoom levels: node, trace, and system.

Grouped Query Experts puts mixture-of-experts routing inside attention — Query-head expert routing — What does it mean?
Grouped Query Experts adds a per-token router that turns on only a few of attention's query heads — keeping every key-value head dense, so the KV cache is unchanged.
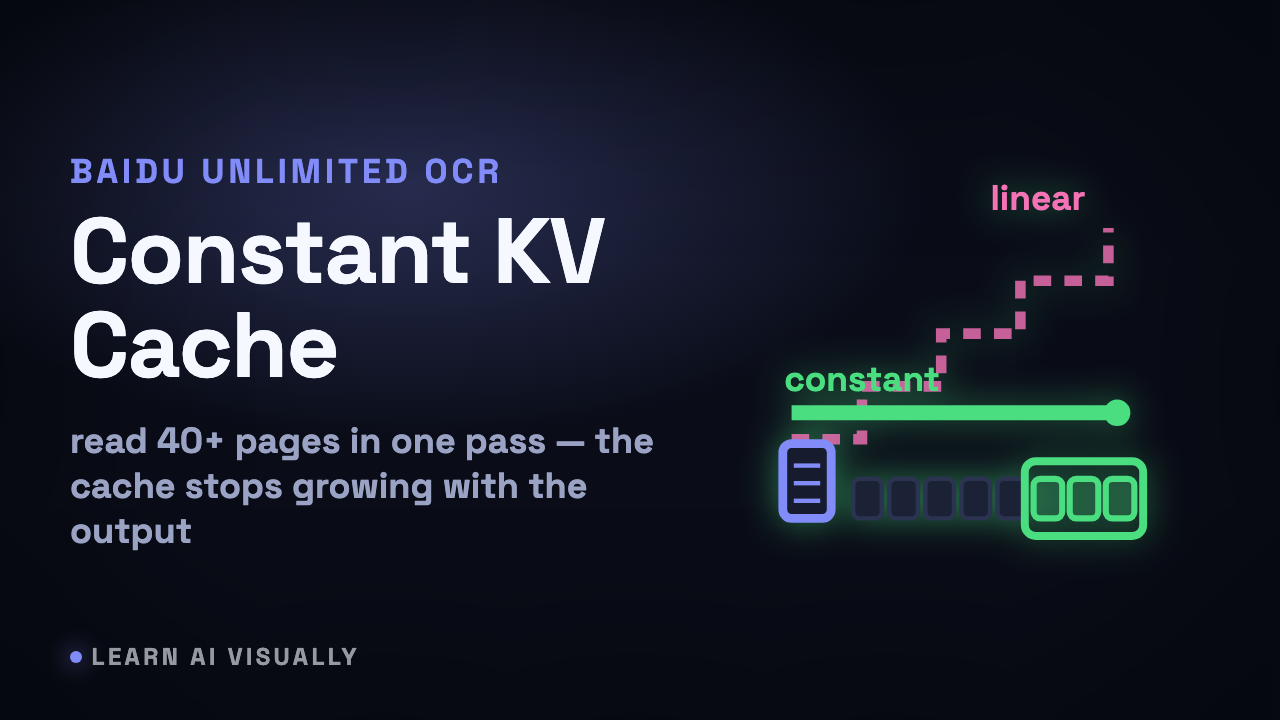
Baidu Unlimited OCR holds the KV cache constant for 40+ pages — Reference Sliding Window Attention — What does it mean?
Baidu's Unlimited OCR swaps decoder attention for R-SWA — each token reads the whole document plus only the last 128 outputs — so the KV cache stays constant across 40+ pages.
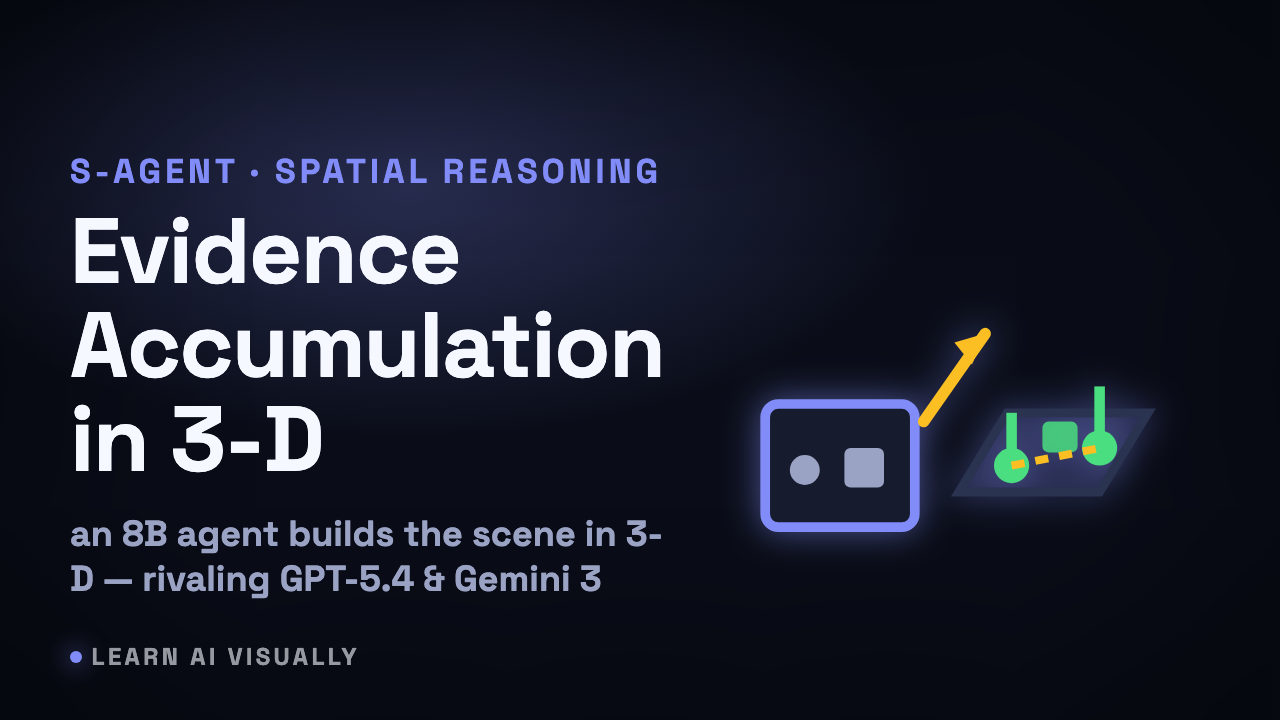
S-Agent: spatial tool-use makes an 8B agent rival GPT-5.4 on spatial reasoning — Spatio-temporal evidence accumulation — What does it mean?
S-Agent makes a VLM a planner directing tools to build one shared 3-D model of a scene — an 8B agent then rivals GPT-5.4.
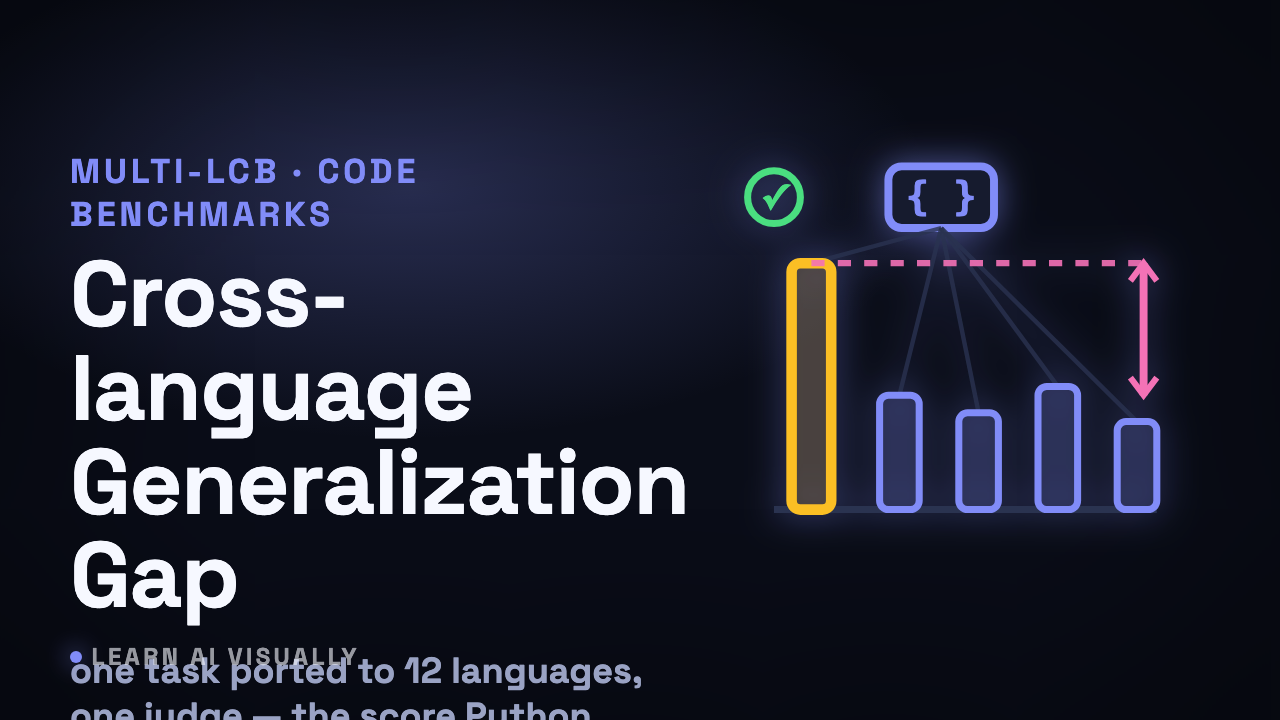
Multi-LCB extends LiveCodeBench to 12 languages — Cross-language generalization gap — What does it mean?
Multi-LCB ports each LiveCodeBench task into 12 languages with one judge, so a score drop measures pure cross-language generalization.
GLM-5.2 becomes the top open-weights model — Active vs total parameters — What does it mean?
GLM-5.2 lists 744B total but 40B active parameters — two numbers that decode different costs: the memory you hold vs the compute you pay per token.