AI Explained
Plain explanations of trending AI concepts, with live visualizations.
EdgeBench measures scaling laws for agents learning in the wild — Environment-learning scaling law — What does it mean?
EdgeBench watches agents keep learning on the job and fits one clean curve to how they improve: a log-sigmoid law with R²=0.998.

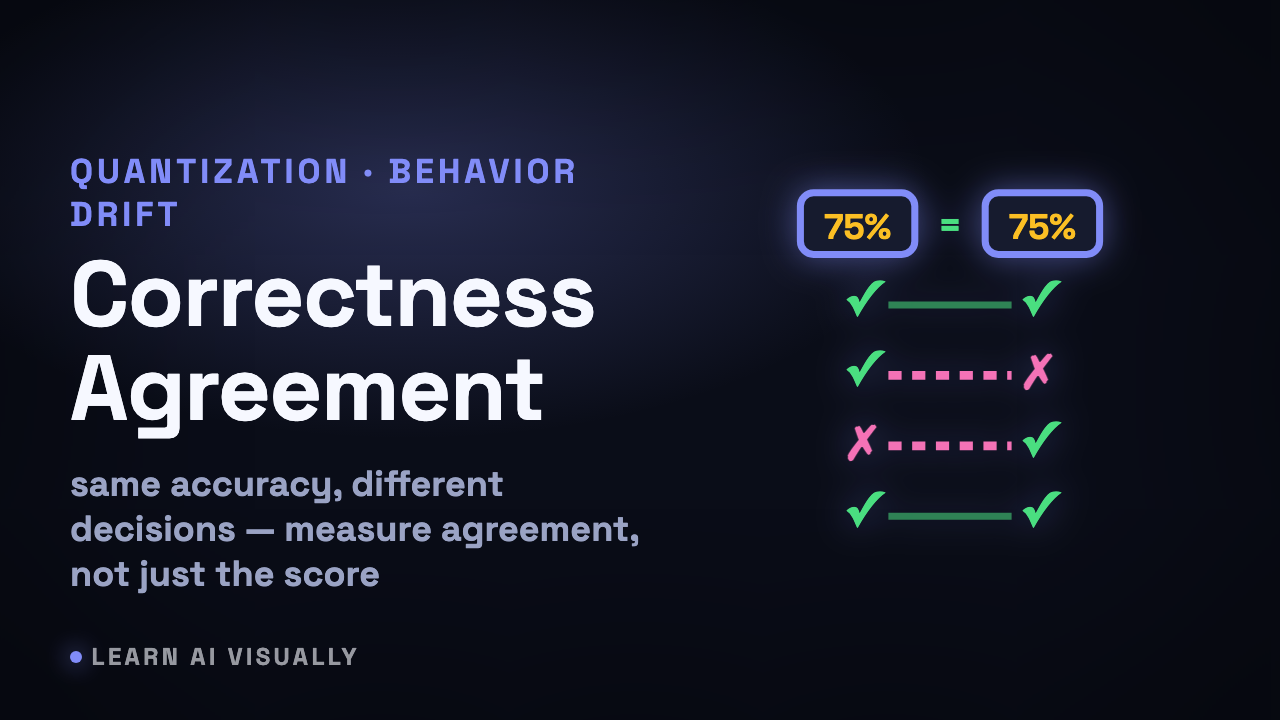
Quantization study finds accuracy can hide behavior drift — Correctness agreement — What does it mean?
A quantized LLM can keep the same accuracy yet change which answers it gets right — correctness agreement measures that hidden drift.
Proactive memory agent counters long-horizon state decay — Memory-grounded reminder injection — What does it mean?
A second agent watches a long task, keeps a memory bank, and re-injects a buried instruction at the right moment — lifting pass@1 without touching the action agent.

NVIDIA Audex — Unified audio-text token space — What does it mean?
Audex is one text decoder that also hears and speaks: audio shares the token space of text, with little to no drop in text skill.
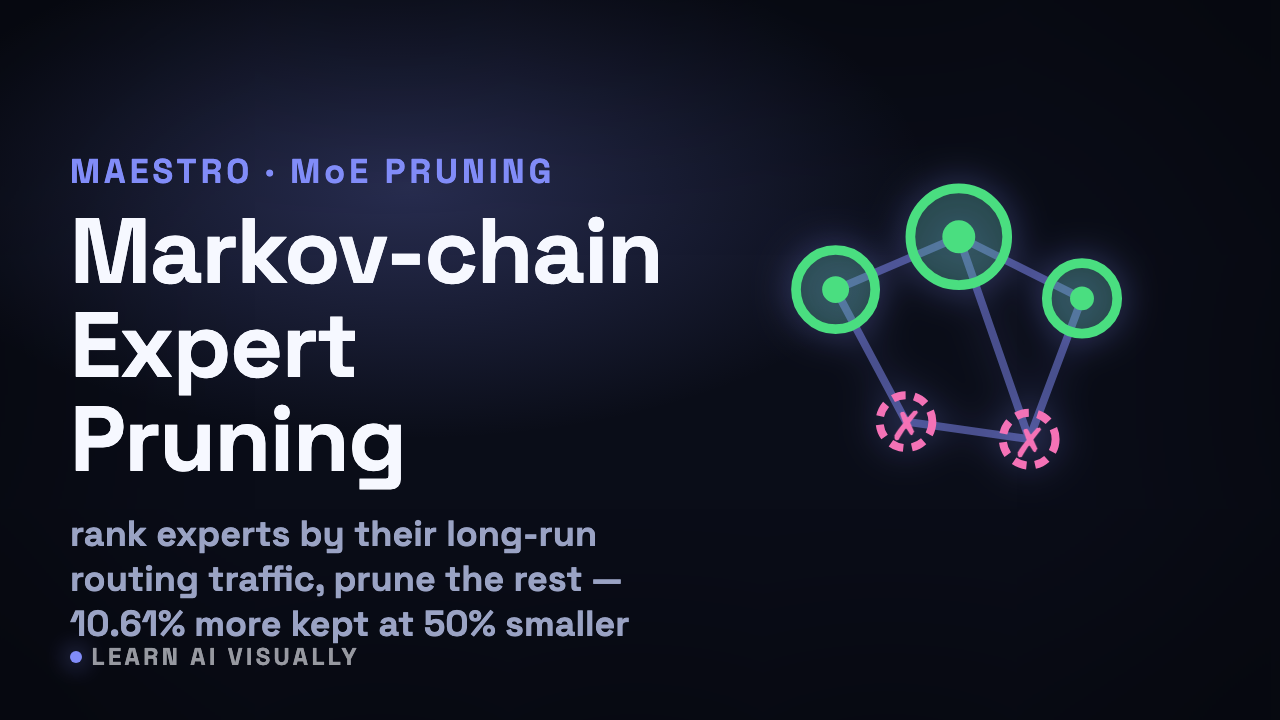
MAESTRO prunes MoE experts with routing-aware Markov chains — Markov-chain expert pruning — What does it mean?
MAESTRO models MoE routing as a Markov chain, ranks experts by their long-run share of traffic, and prunes the rarely-visited ones — keeping up to 10.61% more performance at 50% compression.
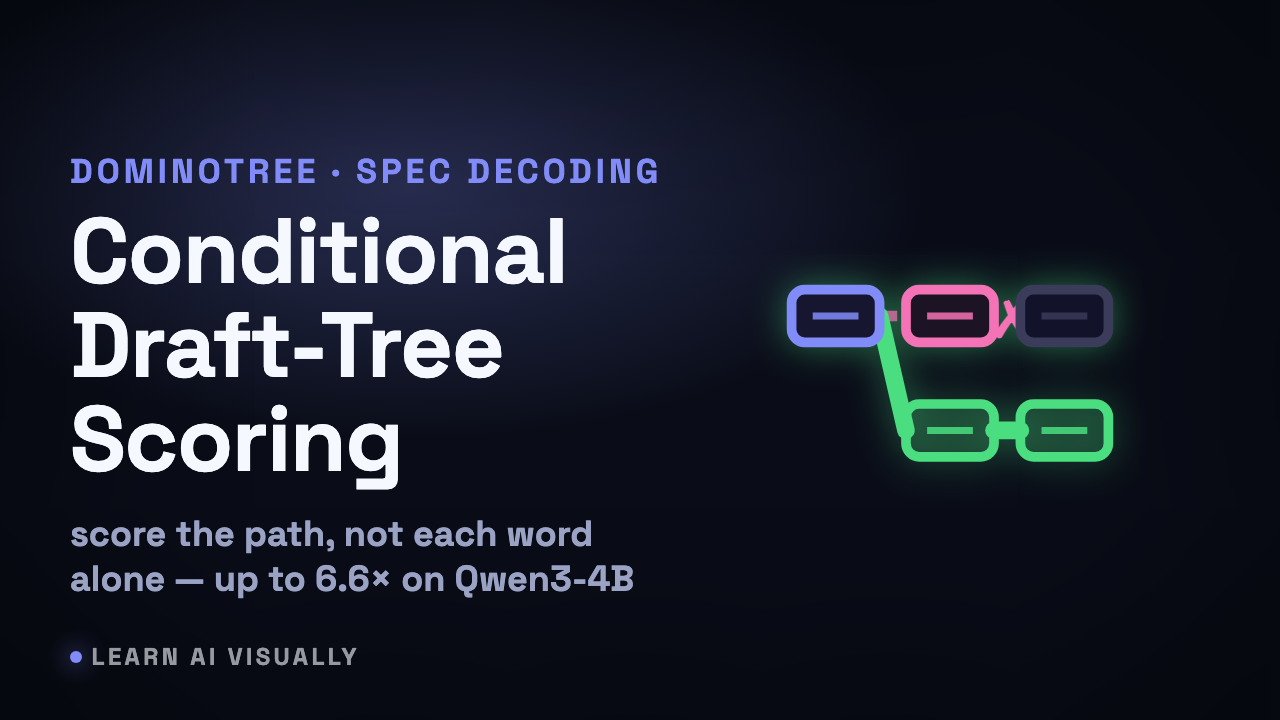
DominoTree speeds speculative decoding with conditional draft trees — Conditional draft-tree scoring — What does it mean?
DominoTree scores speculative-decoding draft trees by how well each token follows the last, not one token at a time — up to 6.6× on Qwen3-4B.
TF-Engram uses SSD-backed phrase memory for train-free LLM recall — Predictive prefetching that hides SSD latency — What does it mean?
TF-Engram stores phrase memories across GPU-DRAM-SSD and prefetches them so a slow SSD read overlaps decode instead of stalling it.
OpenAI finds about 30% of SWE-Bench Pro tasks broken — Benchmark task validity — What does it mean?
OpenAI audited SWE-Bench Pro and found ~34% of tasks broken — a benchmark's pass rate only means something if its tasks are valid.

Mistral releases Robostral Navigate for single-camera robot nav — Pixel-waypoint action space — What does it mean?
Robostral Navigate steers a robot from one RGB camera by predicting a pixel in the image to move toward — no depth sensor or LiDAR, and it still hits 76.6% on R2R-CE.

Multi-agent attacks slip past per-agent monitors (FakeLab) — The fragmentation effect — What does it mean?
Split a malicious goal across a team of agents and each trace looks harmless, so a monitor that checks agents one at a time can miss it.

DeLS-Spec adds short-context heads to block drafting — Long-short logit fusion — What does it mean?
DeLS-Spec fuses a short-context head into a block drafter, discounting common words, so a fast block draft finally picks up the local context its parallel guesses skipped.
AWS maps MCP tool-design tradeoffs for agents — Tool design as context engineering — What does it mean?
AWS reframes MCP tool design as context engineering — tighten schemas, trim responses, lazy-load detail, and at the limit hide the whole workflow behind one endpoint.
